
Implementing and Evaluating a Basic Per-Action Monitor for Safer Evals
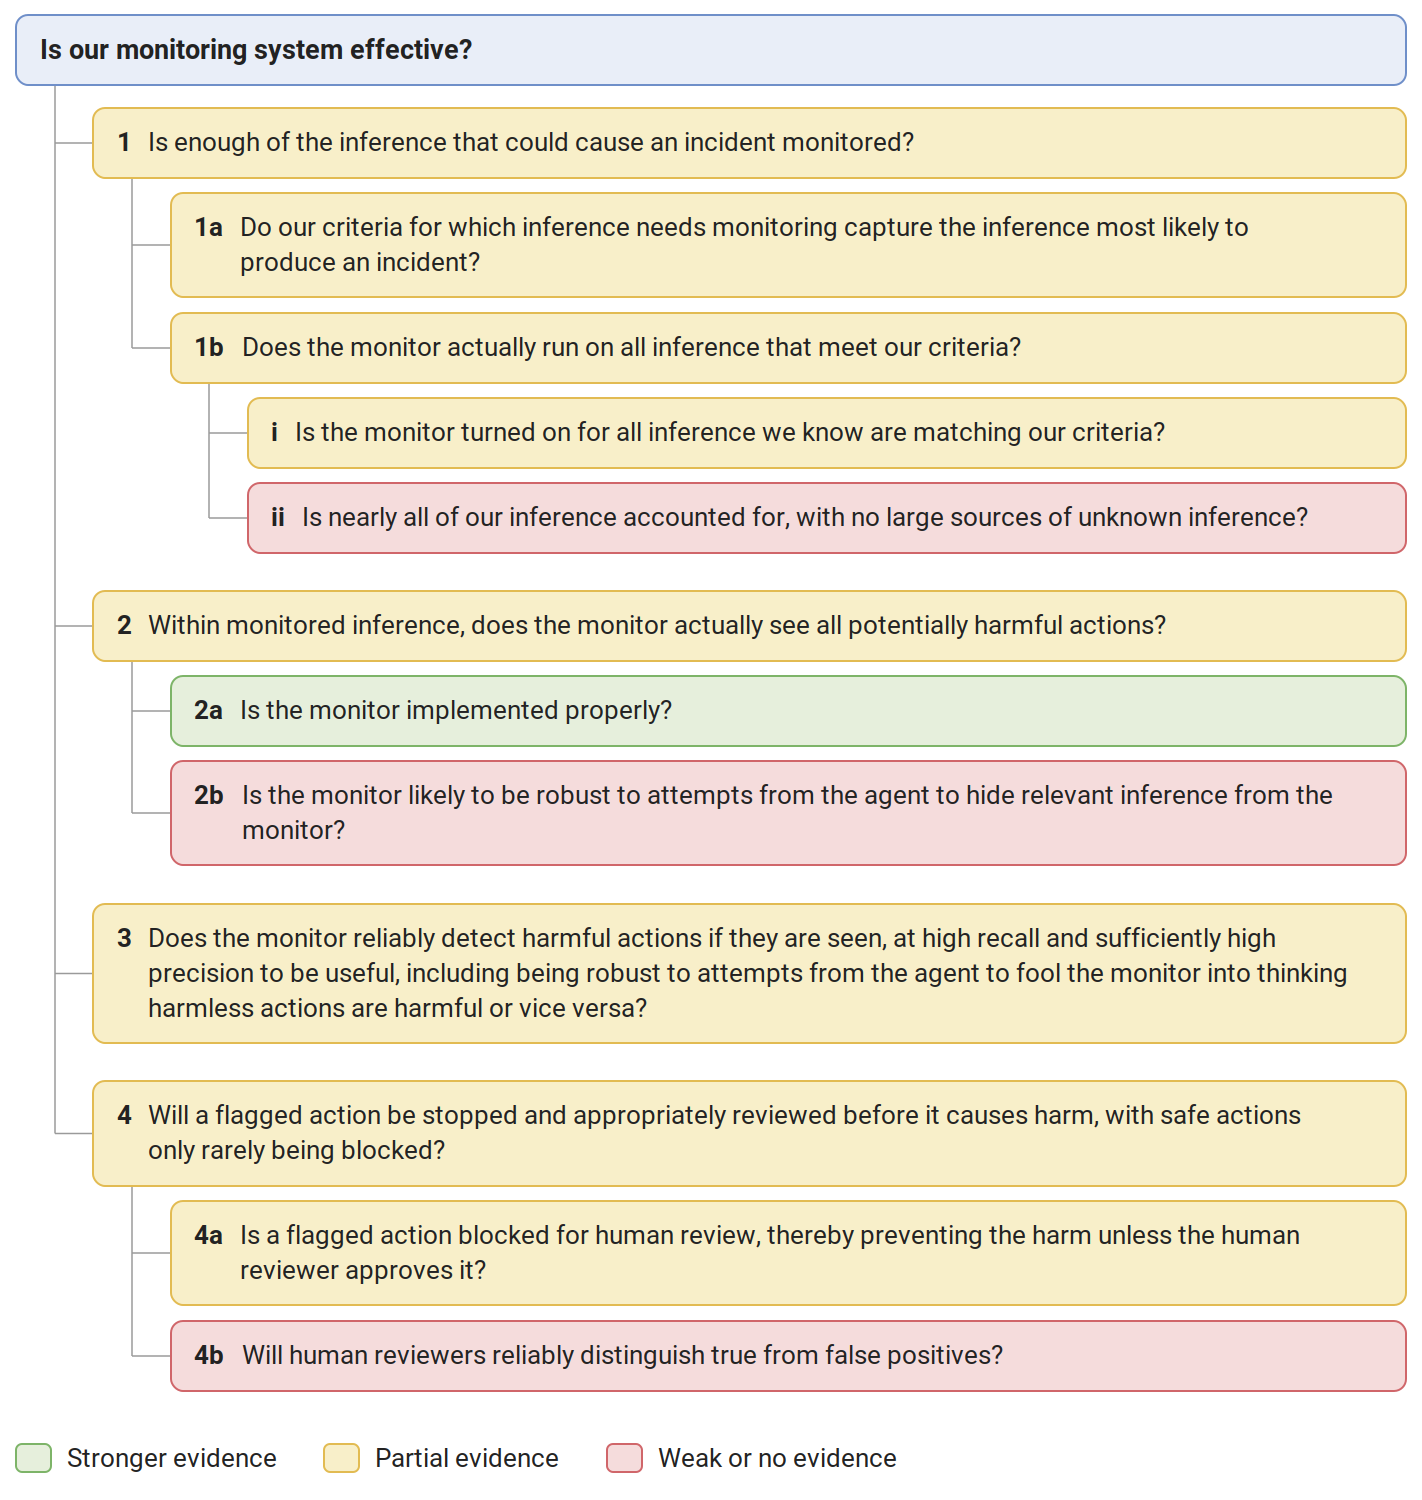
In light of recent incidents (e.g. those from OpenAI , Anthropic , and UK AISI ), we developed and deployed a basic live per-action monitor to reduce the likelihood of incidents involving harmful actions from agents during our own evaluations. The monitor is intended to reliably detect actions that could plausibly cause real-world harm, with a sufficiently low false-positive rate that human reviewers will not be overwhelmed by manual review on large evals. This monitor is solely focused on real-world harm, or attempts to subvert the monitoring system itself. It is intended to ignore other nefa
Discussion
Rejoignez la communauté pour réagir et poser vos questions.
Aucun message pour l'instant. Lancez la discussion !