
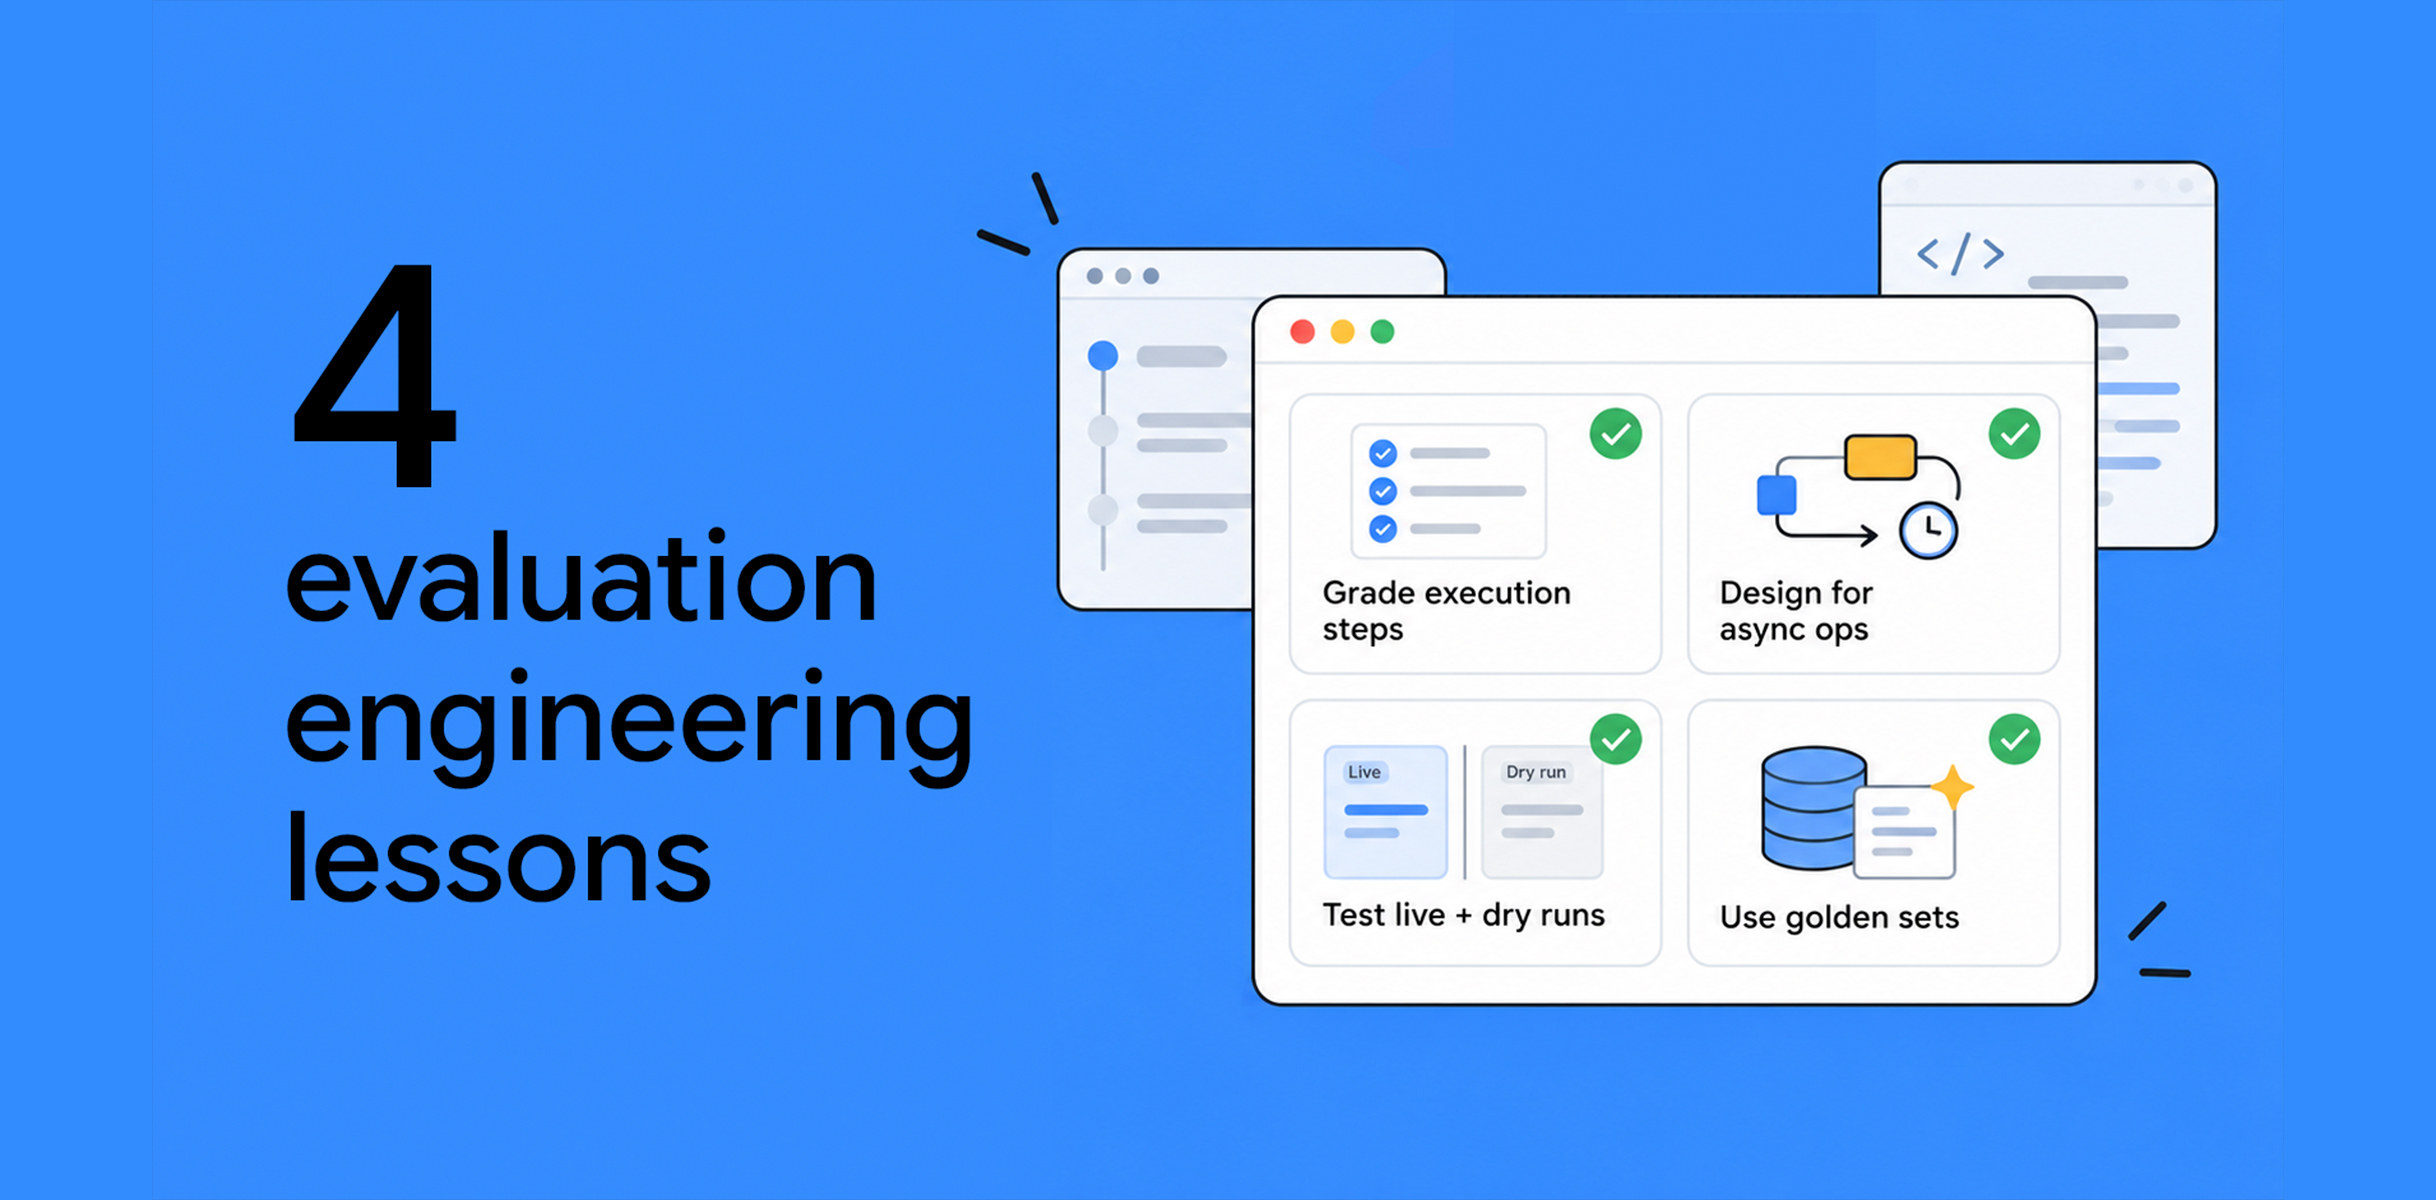
Four evaluation engineering lessons learned from building agent plugins
The real challenge of building an agentic system isn't the construction, it's the measurement. Evaluation engineering is a critical foundation for building reliable AI systems. Setting up systematic, repeatable tests to measure your agent’s true behavior can be the difference between shipping a tool you can trust and one that silently breaks, fails to call APIs, or makes mistakes. I’ve run evaluation engineering initiatives for years at Google and developing the newly released Google Cloud Developer plugin served as a live testbed to stress-test these key principles across real-world developer